# Subtext > Session replay, built for agents. Subtext captures every production session cheaply, then gives the coding agent you already run the tools to open one, inspect the moment it broke, and find the root cause. Evidence an agent acts on, not a video a human watches. This file is the full text of https://subtext.fullstory.com: the product overview, the plans, and every published blog post, newest first. The documentation is a separate set, published as one file at https://subtext.fullstory.com/docs/llms-full.txt and indexed at https://subtext.fullstory.com/docs/llms.txt. # Overview Install with `npx @subtextdev/subtext-wizard`. Sign up at https://app.fullstory.com/subtext/signup. The free plan is 10,000 captured sessions and 100 agent credits a month, with no credit card. Agents connect to the MCP server at https://api.fullstory.com/mcp/subtext, which requires authentication. The install wizard configures it, and https://subtext.fullstory.com/docs/install/overview covers doing it by hand. Subtext is a standalone, self-serve product from Fullstory. You install a capture snippet, connect your agent over MCP or the CLI, and your agent reviews real production sessions. Free to start: no credit card, no seats, no feature gates. Subtext is not a coding agent. You keep the harness you already run (Claude Code, Cursor, Codex, Devin, or your own) and Subtext supplies the session context it has been missing. The category is Agentic Session Review. ## What a session gives the agent A captured session is exposed as tools an agent calls, not a player a human scrubs: screenshots, the accessibility tree, DOM snapshots and diffs, console logs, network activity, and page and route context at any timestamp. ## How an agent reviews a session Review works the way a good engineer uses a map. The agent zooms out to the shape of the whole session (friction, error clusters, network failures), toggles layers (user actions, console, network), then zooms in to a single timestamp or to the diff between two timestamps. The goal is attention: put the least context needed to answer the question in front of the agent, and leave the rest out. ## The workflow 1. **Capture.** A lightweight snippet captures full production sessions, cheaply enough to keep all of them instead of sampling a fraction and hoping the bug was in it. 2. **Link.** A setup prompt drops Subtext session links into the tools your agents already read: Sentry, Datadog, PostHog, Mixpanel, LangSmith, OpenTelemetry, Intercom, Linear, support tickets, traces, PRs. 3. **Review.** Your agent opens the session, inspects the moments that matter, works out what happened, and takes action: files the fix or hands over the finding. ## Common use cases - **Error investigation.** A Sentry or Datadog alert links to the exact session a real user hit, so the agent starts from evidence instead of a stack trace. - **Agent trace review.** A flagged LangSmith run or OpenTelemetry trace resolves to the session behind it. - **Support triage.** An Intercom conversation or a Linear issue entering triage triggers an agent session review before a human reads the ticket. - **Conversion drop-off.** Filter a drop-off cohort in ClickHouse, PostHog, or Mixpanel, then let the agent review those sessions. ## Install Run `npx @subtextdev/subtext-wizard` from your project root. The wizard detects your agent and framework, injects the capture snippet, configures the MCP server, and registers skills in one interactive session. Manual and per-framework instructions (Next.js App Router, React, Vite, Remix) are in the docs. ## Privacy Form inputs are masked from the moment you install. Two layers of control on top of that: code-first redaction with the `fs-mask` and `fs-exclude` classes, and config-first rules your agent proposes from a PII scan for a human to approve. Sessions can be deleted outright. ## Pricing model Two meters. Capture is generous and cheap, because capture is the part that has to be always-on. Agent credits are the value metric: you spend them only when an agent reviews a session. A full agent session review costs 10 credits, and a quick review summary costs 1. Session retention is 30 days. ## What Subtext does not do - It does not write your code. Bring your own agent. - It has no session-list UI for humans to browse. Sessions are reached by link, from the tool that surfaced the problem. - It is not a Fullstory add-on. Subtext has its own signup and billing, and does not run on the same site as Fullstory. Fullstory customers get agentic session review through StoryAI Premium instead. ## Compatibility Any agent that speaks MCP or can run a CLI. Claude Code, Cursor, and Codex work out of the box, and your own harness plugs in the same way. ## Plans | Plan | Price | Captured sessions / month | Agent credits / month | Agent session reviews / month | | --- | --- | --- | --- | --- | | Free | $0 | 10,000 | 100 | 10 | | Starter | $50/mo | 50,000 | 1,000 | 100 | | Team | $250/mo | 500,000 | 10,000 | 1,000 | Sign up at https://app.fullstory.com/subtext/signup. Capture pauses at your session cap and agent tools pause at your credit cap; upgrading applies the new limits immediately. Usage-based pricing above Team is not available yet. Full plan details: https://subtext.fullstory.com/pricing # Attention Is a Zoom Source: https://subtext.fullstory.com/blog/attention-is-a-zoom Published: 2026-07-24 Author: Joel Webber and Clint Ayres Topic: research Every question you ask a session collapses to the same handful of moves: map, then zoom. _A calculus of session review._ A good session replay holds the user's trajectory: every click, navigation, network request, and console log. But dumping all of it into an agent's context window puts stress on attention. What's the important signal? Is repeated data meaningful? Are these errors impacting the user experience or just noise? Agents are great at summarizing data sets, but not at deciding what to summarize. Session review needs a calculus: a pattern of progressive disclosure for revealing what happened. Every question an agent asks reduces to two moves: map the experience, then zoom into the details. Since each question maps to a specific set of tools, any query becomes a formula the agent can reuse. ## Two data sets to review A session review happens over two data sets: a signal stream and visual snapshots. A **signal stream** is everything that happened, in order and when: the user's interactions, the navigations between pages, the network requests, and the browser console. Anything that failed is also flagged as an error. A **snapshot** is the pixels at any instant, plus a text snapshot of the on-screen elements. An agent reviews across both data sets: it zooms through the signal stream, or views snapshots and pixels at specific moments. We use _zoom_ for the motion of attention: zoom in for more detail, zoom out for context. Every zoom call costs tokens, so the agent budgets attention by controlling how much resolution is returned. Let's open the session and follow the agent's moves. _Interactive: click to explore each figure below._
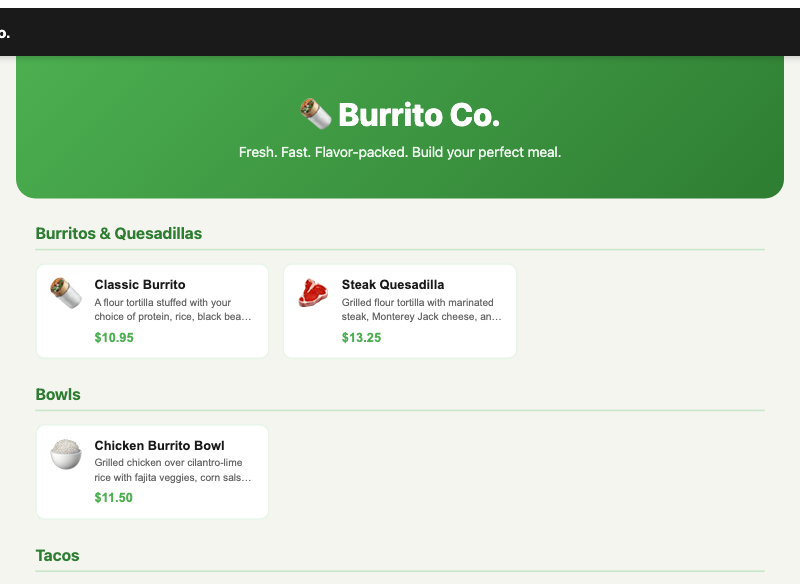
The Burrito Co. menu, where the session begins
[main] .burrito-main [heading] "🌯 Burrito Co." [paragraph] "Fresh. Fast. Flavor-packed." [heading] "Burritos & Quesadillas" [button] "🌯 Classic Burrito $10.95" .menu-card [button] "🥩 Steak Quesadilla $13.25" .menu-card [heading] "Bowls" [button] "🍚 Chicken Burrito Bowl $11.50" .menu-card [heading] "Tacos" [button] "🌮 Veggie Tacos $9.75" .menu-card
Where the session begins. Every snapshot is two halves: the pixels (left) and the text snapshot the agent reads (right).
## The map: always the entry point Before an agent can zoom anywhere in the signal stream to answer a question, it needs to orient itself to where the data is clustered. Opening the session hands the agent a map and a digest: the user's flow through the app, counts of everything captured, and the signals rolled up at each stop. Open the session and this is what comes back: ``` ## Map · 32 events · 0.0s–47s · 1 page(s) flow: /apps/burrito/ ▸ /item/ ▸ /cart/ ▸ /apps/burrito/ ▸ /item/ ▸ /cart/ ▸ /checkout/ ▸ /confirmation/ phases: /apps/burrito/[2] -> /item/?id=classic-burrito[4] -> /cart/[2] -> /apps/burrito/[2] -> /item/?id=chips-guac[2] -> /cart/[2] -> /checkout/[16] -> /confirmation/[2] kinds: navigation 8 interaction 19 network 3 (2 err) console 2 (2 err) tags: error:4 # /apps/burrito/ (opened) page-load ×1 · interaction ×1 # /item/?id=classic-burrito (navigated) interaction ×3 # /cart/ (navigated) interaction ×1 # /apps/burrito/ (navigated) interaction ×1 # /item/?id=chips-guac (navigated) interaction ×1 # /cart/ (navigated) interaction ×1 # /checkout/ (navigated) interaction ×11 · network ×2 (2 err) ("POST /api/checkout") · console ×2 (2 err) # /confirmation/ (navigated) network ×1 ("POST /api/checkout") # /confirmation/ (closed) ``` The map orients the agent; the digest shows the signals cluster at checkout, where all four errors are. ## How to take a closer look With the map in hand, the agent can request more data, in greater detail, at any point in the session. Any signal can be shown to the agent at one of four grains, coarse to fine:
map always returned · counts everything, matched or not · not a grain
  1. digest one line per kind, like network ×3 (2 err) ~60 tokens
  2. standard the readable transcript, benign repeats merged ~460 tokens
  3. machine every signal, nothing merged ~530 tokens
  4. detail every signal plus its payload: headers, bodies, stack traces ~760 tokens
Bar length is the token cost of reading the whole burrito session at that grain (est.). Pick the correct rung to progressively disclose more information.
Visual snapshots have their own dial as well, a `lens`, that controls which elements come back in the text snapshot; this doesn't affect the pixels.
  1. interactive only what you can act on: buttons, inputs, links (5 elements) ~30 tokens
  2. visible everything on screen (12 elements) ~120 tokens
  3. full every element, plus CSS selectors (15 elements) ~370 tokens
Bar length is the token cost of the text snapshot at each lens (est.). The pixels are identical; only the text snapshot changes.
Each snapshot in this post is shown with both the pixels and the text snapshot. The `lens` dial decides how much of that text snapshot comes back to manage tokens; the pixels never change.
## Naming what to look at An agent asks for signals by naming which ones it wants and in how much detail. For example `{network: "machine"}` means every network signal, over a time period, with no rollups. Names for signals can overlap. A failed request is both `network` and `error`, and when a signal matches two, the finer grain wins. ## Answering a question Now put the calculus to work on a real report. The agent picks up a ticket: "A shopper says checkout is broken and they couldn't place their order." To find out why, it asks four questions: what did they do, what went wrong, what did they see, and what did the network do?
Read `;` as **then**. Every answer has the same shape: $\mathrm{map}$ first, then a $\mathrm{zoom}$.
### What happened? Where the user went and what they did. $$\mathrm{map} \;;\; \mathrm{zoom}(\{\mathtt{navigation} \mapsto \mathtt{standard},\ \mathtt{interaction} \mapsto \mathtt{standard}\})$$
# /apps/burrito/ (opened)
3120ms  click "🌯 Classic Burrito"
6480ms  click "steak"
8210ms  click "guacamole (+$2)"
10360ms click "Add 1 to Cart"
13840ms click "Continue Shopping"
# … Chips & Guacamole added …
# /checkout/
25640ms click "Continue to Payment →"
28080ms change card "•••• 0000"
        click "Continue to Review →"  (×3)
        click "Place Order · $17.17"  (×3)
        click "Try Again"             (×2)
42880ms change card "•••• 4242"
This whole visit is readable to the agent as a story: the user browses, customizes, adds to cart, checks out, and a retry that hints something failed. ### What went wrong? View just errors at the finest grain across the whole session. $$\mathrm{map} \;;\; \mathrm{zoom}(\{\mathtt{error} \mapsto \mathtt{detail}\})$$ It lands on the two declines, full failing payload, nothing else:
# /checkout/
33269ms POST /api/checkout => 402 (149ms)
    req-headers: content-type: application/json
    req:  { card_last_four: "0000", total: 17.17 }
    rsp-headers: content-type: application/json · content-length: 125
    rsp:  { error: "card_declined", code: "do_not_honor", card_last_four: "0000", message: "The card issuer declined the transaction." }
33270ms console.error "checkout declined: 402 do_not_honor"
38159ms POST /api/checkout => 402 (144ms)
    req-headers: content-type: application/json
    req:  { card_last_four: "0000", total: 17.17 }
    rsp-headers: content-type: application/json · content-length: 125
    rsp:  { error: "card_declined", code: "do_not_honor", card_last_four: "0000", message: "The card issuer declined the transaction." }
38160ms console.error "checkout declined: 402 do_not_honor"
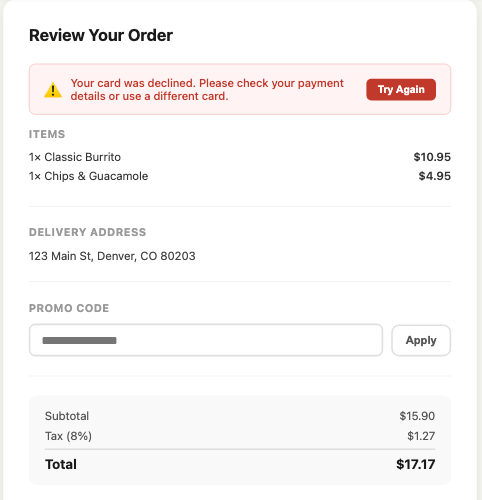
The agent sees two failures out of thirty-two signals: the card was declined twice, same card both times. ### What did they see? The stream says what happened; pair it with a snapshot at each moment and you also see what the shopper saw. $$ \begin{aligned} \mathrm{map} \;;\; \Big(\ &\mathrm{zoom}(\{\mathtt{navigation} \mapsto \mathtt{standard}, \\ &\qquad \mathtt{interaction} \mapsto \mathtt{standard}, \\ &\qquad \mathtt{error} \mapsto \mathtt{detail}\}), \\ &\{\mathrm{snapshot}(\mathrm{moment}_i)\}_{i=1}^{N}\ \Big) \end{aligned} $$
The review step with the card-declined banner
[main] .burrito-main [heading] "Review Your Order" [alert] "⚠️ card declined…" .error-banner [button] "Try Again" .retry-btn [heading] "ITEMS" [text] "1× Classic Burrito $10.95" [text] "1× Chips & Guacamole $4.95" [heading] "DELIVERY ADDRESS" [paragraph] "123 Main St, Denver, CO" [heading] "PROMO CODE" [textbox] "•••• •••• •••• *" .form-input [button] "Apply" .btn-secondary [text] "Total $17.17" [button] "← Back" [button] "Place Order" .btn-primary
The review step, card declined: what the shopper saw, and the text snapshot the agent read.
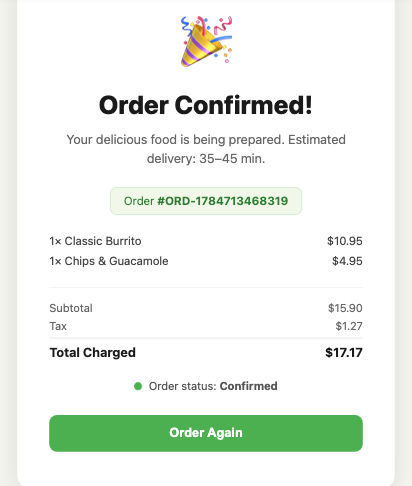
Next the user swaps in a good card and the order goes through.
The order confirmed once a good card was used
[main] .burrito-main [heading] "Order Confirmed!" [paragraph] "Your food is being prepared…" [text] "Order #ORD-1784713468319" [text] "1× Classic Burrito $10.95" [text] "1× Chips & Guacamole $4.95" [text] "Total Charged $17.17" [text] "Order status: Confirmed" [button] "Order Again" .btn-primary
The order confirmed once a good card was used.
### Devtools The whole network and console picture across the session, one line per request and log. $$\mathrm{map} \;;\; \mathrm{zoom}(\{\mathtt{network} \mapsto \mathtt{machine},\ \mathtt{console} \mapsto \mathtt{machine}\})$$ This is where the successful retry shows up alongside the two declines. Zoom any request to detail for its full headers and body.
# /checkout/
33269ms POST /api/checkout => 402 (149ms)
33270ms console.error "checkout declined: 402 do_not_honor"
38159ms POST /api/checkout => 402 (144ms)
38160ms console.error "checkout declined: 402 do_not_honor"
# /confirmation/
46540ms POST /api/checkout => 200 (150ms)
## Attention is a zoom Every question and answer above has the same shape. We start with a map (cheap and whole) and then zoom into signals or pixels to understand the root cause. $$\textbf{question} = \mathrm{map} \;;\; \mathrm{zoom}(\dots)$$ --- Try it on your own session. ```bash npx @subtextdev/subtext-wizard ``` # A map, not a movie Source: https://subtext.fullstory.com/blog/a-map-not-a-movie Published: 2026-07-15 Author: Chip Lay Topic: product A good engineer never watches a session replay end to end. They orient, zoom, and inspect one layer at a time, the way you use the map in your pocket. Agentic Session Review gives your agent that same map. A good engineer doesn't watch a session replay from beginning to end. They orient. Skim the timeline for the anomaly. Jump to the moment. Open devtools. Read the console and stack trace at that timestamp. Compare what the page looked like before and after. Zoom out, zoom in, one layer at a time, until the answer is small enough to hold in their head. There's a piece of software that perfected this motion years ago: the map in your pocket. ![Google Maps at three levels of detail: a city map, a street-level satellite view, and the traffic layer](/blog/images/map-not-movie-1.webp) **A map focuses [attention](https://arxiv.org/abs/1706.03762) without losing context.** Google Maps compresses the planet onto a screen, then lets you move fluidly between levels of detail. Start with the city. Zoom into the neighborhood. Drop to street level. Toggle the traffic layer when traffic is the question. That's the idea behind **Agentic Session Review** in Subtext. We've given the agent you already use a map of what happened in a real production session. The agent can start with the whole session: where friction appears, where errors cluster, where the experience went off course. Then it can zoom into a timestamp, compare two moments, or inspect a specific layer—user actions, console output, network calls, pixels, or the accessibility tree. These are MCP tools, not a dashboard. **Your agent drives the investigation, not ours.** Most attempts to automate session replay put someone else's model between you and the session. The captured session goes to a model you didn't choose, the model decides what matters, and you get its conclusion. From there, one of two things happens. If it summarizes the session upfront, it compresses too early. "The user struggled at checkout" may be true, but the root cause could be a config response missing one field two events before the crash. You can't recover a detail the summary decided wasn't important. If the model processes the replay frame by frame, it preserves the detail but wastes attention. A thousand nearly identical frames pour into the context window when the signal lives in three of them—plus a network request the pixels can't show. Anyone who has scrubbed replay at 2x knows the feeling. Trevor Loucks [put it in words](https://x.com/MeTrevorLoucks/status/2063927468461805868) we've never topped: _"Watching session replays is my personal hell. I wish the ROI wasn't so high."_ Agents don't hate it at all. They'll dutifully process every frame you pay for, which is worse. 💸 Either way, a model you don't control decides what you see. Subtext gives the agent you already use a third option: a map. It can compress the session without flattening it, holding only what the question needs while keeping the underlying evidence one tool call away. ![The same three map views mapped onto Agentic Session Review: Orient, Zoom, and Layer](/blog/images/map-not-movie-2.webp) Of course, a map is only as good as its survey data. Subtext draws on Fullstory capture: a decade of recording sessions faithfully enough to reconstruct any moment and cost-effective enough that you can leave it running everywhere. An agent can't investigate details that were never preserved. That changes what session replay is for. Session replay gave humans a way to watch what happened. **Agentic Session Review gives agents a way to investigate it—and act on what they find.** As James Friend, an engineer at [Clay](https://www.clay.com/) and one of our design partners, put it: > "We run our Sentry alerts through Subtext, so instead of a vague exception, we get the actual user impact, repro steps, and a validated fix. The screenshots of the broken UI a real user experienced motivate the owning team to prioritize it." Subtext is available today. Give your agent the map it needs to see, diagnose, and fix what actually happened. ```bash npx @subtextdev/subtext-wizard ``` Not ready to install? Take it for a spin in the [playground](/playground). # Introducing Subtext: Session Replay → Agentic Session Review Source: https://subtext.fullstory.com/blog/introducing-subtext Published: 2026-07-15 Author: Scott Voigt Topic: company Today we're launching Subtext and opening the era of Agentic Session Review. For a decade Fullstory captured behavioral truth so humans could watch replays. It turns out that data is even more valuable to the agents you already use. Today, we're proud to launch Subtext and usher in the era of Agentic Session Review (ASR). The first ten years of Fullstory were really about helping human teams find, forensic (I verbed it), and fix bad digital experiences. Fullstory led the way with a radical approach to safely capture and structure behavioral data, and yes, the best damned session replay in the world. It is still the best by a country mile (source: biased founder). Session Replay, when we launched it way back when, was like magic — an easy and powerful way for our customers to truly understand and empathize with their visitors. That remains true today, and it isn't going anywhere. Humans still need to watch things. But something else is happening now. It's not _just_ humans who need to watch things anymore. > Within the next 6 months, AI agents will watch more sessions than every human combined. They won't scrub through a playback moment-to-moment the same way a human would. They'll do what we are calling Agentic Session Review, navigating structured, queryable behavioral truth: what happened, in what order, on what element, with what state around it. This behavioral truth is exactly what Fullstory has been capturing under the hood for a decade and refined across billions of real sessions, not stitched together from an open-source recorder last quarter. We built it so humans could watch a replay and perform deep analytics. It turns out it's even more valuable as raw material for a model that can reason over structure directly and never gets bored or distracted after watching the 100th replay. That's the bet behind Subtext: the data we've always captured is better appreciated by AI than it ever was by humans. Subtext is a behavioral capture and delivery layer built for agents as the primary user persona. It lets AI agents you already use (Claude Code, Cursor, Codex, Devin, or your own harness) open and investigate a session directly, with tools designed for progressive disclosure: reading console errors, network calls, DOM state, and heuristic signals galore (flex: remember Fullstory created [Rage Clicks](https://tsdr.uspto.gov/#caseNumber=87521863&caseSearchType=US_APPLICATION&caseType=DEFAULT&searchType=statusSearch)). The agent pulls in only what the question needs, one layer at a time, to guide attention. To lead the Agentic Session Review opportunity we created a separate internal team with a simple, slightly uncomfortable charter: design a product as if AI is the primary user, not humans. That clarified a lot. Simple CLI install. Headless. Tools shaped around token efficiency instead of visual polish. Attention management. Make privacy controls increasingly automated. Also, importantly, we rethought pricing to make it super cheap to capture everything, because sampling makes no sense when your user is a model that can process the full picture at scale. If you're building something new, or your team is already leaning into agentic workflows, please give Subtext a try: `npx @subtextdev/subtext-wizard` or head on over to [subtext.fullstory.com](https://subtext.fullstory.com/). It's free to start. Tell us where it breaks or where we can improve it. We've got an exciting backlog of things and will be shipping updates fast. Stay tuned! # Build Together Again Source: https://subtext.fullstory.com/blog/build-together-again Published: 2026-03-25 Author: Chip Lay Topic: company AI gave everyone the power to build software. It forgot to give them a place to build it together. I've been a designer, a front-end engineer, and now a product leader. I've sat in every seat of what I think of as the triad: the relationship between design, engineering, and product that makes software happen. I'm watching it come apart. Not because people stopped caring, but because AI handed everyone a set of capabilities that used to belong to someone else, and nobody figured out how the team is supposed to work now. ## The triad The way it used to work: Product figured out what to build and why. Design figured out how it should look and feel. Engineering figured out how to make it real. Each role had a lane, a set of tools, and a handoff point. Product wrote specs. Design made mockups in Figma. Engineering wrote code. The artifacts moved in one direction: idea to mockup to code to production. It wasn't perfect. The handoffs were lossy. Engineers built things that didn't match the mockup. Designers specced interactions that were expensive to implement. PMs changed requirements mid-sprint. We all complained about it constantly. But we understood the system. Everybody knew their role, knew where to look, and knew whose turn it was. Fullstory lived downstream of all of this. After the triad finished its work and the code hit production, Fullstory showed everyone what actually happened. What real users actually experienced, not what the spec said should happen or the mockup promised. Session replay became the shared visual truth that connected support and sales and product and engineering. The one place where everyone on the team was looking at the same thing. ## The disruption nobody talks about The AI conversation in public has been about speed. How fast can agents write code? How many PRs can you ship in a day? How do you 10x your output? That's the story on Twitter and at conferences and in pitch decks. The story inside companies is different. It's emotional and it's messy, and nobody quite knows how to talk about it yet. A designer on your team opens Claude Code and starts building a feature directly. The code works, mostly, but it doesn't follow the component library and the CSS is inline and the accessibility is wrong. It goes into a PR. An engineer reviews it, rewrites half of it, and feels like they're cleaning up after someone who shouldn't have been coding. An engineer uses an AI agent to redesign a settings page. The agent one-shots it. The layout is functional but the spacing is off, the hierarchy is flat, and it doesn't match the design system. The designer sees it in staging and feels bypassed. Nobody asked them. Nobody even showed them. A PM is hacking a prototype in Cursor to prove out a concept. It's impressive for a demo but it's held together with duct tape, and now the CEO saw it and thinks it's the real thing. Engineering has to rebuild it properly and explain why it takes longer the second time. And the agents are the worst offenders. They generate code, create a PR, and move on. No stopping to check whether the experience makes sense. One-shot and ship. Everyone can build now. But everyone's building alone. ## What got lost The triad had friction, but it also had forced alignment. The Figma handoff meant a designer and an engineer had to look at the same mockup and agree on what they were building. The spec review meant product and engineering had to negotiate scope in the same room. The QA cycle meant someone was actually using the thing before it shipped. > AI removed the friction. But it also removed the alignment. When a designer can go straight to code, there's no handoff conversation. When an engineer can generate UI without a mockup, there's no design review. When an agent writes a feature in ten minutes, there's no moment where the team stops and asks: does this actually do what we want? Does it look right? Does the experience make sense? The artifacts that used to force collaboration (the Figma file, the spec doc, the staging environment) still exist, but they're increasingly optional. People skip them because they can. The agent certainly skips them. The result is a PR backlog full of AI-generated code that nobody has properly reviewed for UX quality. Engineers are reviewing code, checking for logic bugs and security issues and performance problems. But nobody is systematically reviewing what users will actually see. Does the button look right? Does the flow make sense? Did the agent put the error message in a place where someone will actually notice it? Code review checks the code. Nobody checks the experience. ## The session replay insight I keep coming back to why Fullstory's session replay worked as well as it did. The obvious answer is that it showed you what users do. But the deeper answer is that it gave the whole team a shared surface. Before session replay, every team had their own version of reality. Support had ticket descriptions. Product had analytics dashboards. Engineering had error logs. Sales had customer quotes from memory. Everyone was describing the same product experience through different lenses, and half the arguments in cross-functional meetings were really just arguments about whose version of reality was correct. Session replay collapsed all of that into one visual artifact. You press play. You watch what happened. The support rep, the PM, the engineer, and the designer are all seeing the same 30 seconds of a user struggling with a checkout flow. No translation layer. No telephone game. > Teams build better when they're looking at the same thing. Not the same dashboard or the same Jira ticket. The same visual experience. That's the thing Fullstory got right, and I think we underestimated how transferable that idea is. ## A new shared surface AI broke the triad, and no amount of process is going to reassemble it the way it was. Designers are going to keep coding. Engineers are going to keep making product decisions. PMs are going to keep hacking prototypes. Agents are going to keep one-shotting features. That genie is out. What's missing isn't the old workflow. It's a shared surface for the new one. Think about what would have to be true for this blurry new triad to actually work. You'd need a place where a PM can describe what they want and see it take shape visually. Where a designer can review what the agent built and annotate the experience, not the code. Where an engineer can see the full context of what's being asked for and why. Where an agent can get visual feedback and iterate with the humans who care about the outcome, instead of one-shotting into a PR and hoping for the best. That surface isn't Figma, which gives you static mockups of something that doesn't exist yet. It isn't GitHub, where you're reading diffs nobody can evaluate visually. And it isn't Slack, where people describe visual problems in text. The collaboration layer needs to be the product experience itself. The running, interactive, visual thing. Session replay is already that for production. The same concept works upstream. I've been working on this at Fullstory. We're calling it Subtext. The product experience becomes the shared surface where the whole team works. An agent builds something and the result is a replayable session that anyone can watch and comment on. A designer sees a spacing problem and their feedback goes back to the agent as structured visual context, not a Slack message. A PM reviews the experience the way a user would, not through a code diff. It's early. We're testing with a handful of teams. But the conviction comes from watching session replay do this same thing for a decade on the production side. Collapse everyone's separate version of reality into one shared visual truth. The build process needs that just as badly, maybe more, now that AI has everybody building at once. ## Why "again" The triad wasn't just a process. It was a way for different kinds of thinkers to contribute to the same product. The designer who sees spatial relationships and hierarchy. The engineer who sees system constraints and edge cases. The PM who sees user needs and market context. The best software I've ever shipped came from those perspectives colliding, not from any single person or agent doing it all alone, no matter how fast. AI made everyone capable of building. What it didn't do is give them a reason to look at the same screen. That's the part we're working on. We built Fullstory to help teams see what users experience after something ships. We're building Subtext to help teams see what they're building while they build it. Same idea. Earlier in the process. More people in the room. That's what "build together again" means. Not going back. Going forward with the thing that actually made the old way work, a shared surface where everyone sees the same product experience, and bringing it into a world where everyone has superpowers and nobody has a process. # Your agent can't see what it built Source: https://subtext.fullstory.com/blog/agents-cant-see Published: 2026-03-05 Author: Chip Lay Topic: product Coding agents write code, spin up previews, and ship PRs. But they still can't perceive their own work, and the humans reviewing it have no good way to talk back. Agentic Session Review fixes both: sessions your agent can read. ![Hero](/blog/images/agents-cant-see-1.jpg) Something weird is happening in software development right now. Coding agents are getting genuinely good at writing code. Claude Code, Cursor, Codex. They can read your codebase, make multi-file changes, run tests, iterate. Cursor's cloud agents are already producing 30% of their own merged pull requests, running autonomously on VMs. The code part is increasingly solved. But here's what keeps nagging at me: these agents are building software meant to be used by humans, and they can't perceive their own work the way a human would. Your agent writes a checkout flow. It can read the HTML it generated. It can verify the DOM structure matches what it intended. It can run Playwright tests against the page. What it can't do is look at the checkout flow and notice that the button color is wrong, the loading spinner feels sluggish, or the layout breaks on mobile in a way that makes users hesitate. The agent is blind to the experience it created. > The agent is building software meant to be used by humans, and it can't perceive its own work the way a human would. This wasn't a big deal when agents were autocomplete tools living inside your IDE, suggesting the next few lines while you watched. You were right there. You could see what was happening. But that era is ending fast. ## Agents are leaving the IDE It's already happening. Cursor shipped cloud agents running on isolated VMs in February. Zed merged headless mode for programmatic AI control. Claude Code runs in terminals, CI pipelines, and cloud environments. The agent doesn't need your laptop anymore. Which means the agent is building in one place and you're reviewing in another. The work happens in a cloud VM. You get a preview link and a pull request. And here we arrive at the actual problem. Not the code. The conversation. ![The middle loop](/blog/images/agents-cant-see-2.jpg) ## The middle loop has no language People are starting to notice. Simon Willison built [Showboat](https://github.com/simonw/showboat) so agents can create executable markdown documents that demonstrate their work, mixing commentary, code blocks, and captured output into a single verifiable artifact. [Rodney](https://github.com/simonw/rodney), his companion tool, gives agents a CLI for browser automation so they can actually drive what they built and take screenshots. He's cataloging what works in his [Agentic Engineering Patterns](https://simonw.substack.com/p/agentic-engineering-patterns) collection. [Agentation](https://agentation.dev) attacks it from the human side: you click elements on your page, add notes, and it generates structured output that helps agents find the exact code you're pointing at. Version 2.0 added an MCP server so agents can fetch your annotations directly. And now there's data to back it up. Annie Vella ran a [six-month longitudinal study](https://annievella.com/posts/the-middle-loop/) with 158 professional engineers across 28 countries and found that 82% are spending less time writing code — but the freed-up time isn't flowing upstream into design and architecture the way everyone assumed. It's compressing across almost every task category. What's growing instead is what she calls "supervisory engineering work": directing AI, evaluating its output, correcting it when it's wrong. The creation-to-verification shift was statistically significant across her study period. Engineers are more productive (84% reported gains), but the proportion reporting negative developer experience nearly doubled, from 14% to 27%. She calls it the productivity-experience paradox. The work changed, but the tools didn't change with it. These tools and findings all circle the same insight: agents need to _show_ their work, and humans need better ways to _point at_ what's wrong. I think both are right, and I think the problem is bigger than any single tool can solve. There are three loops in agent-assisted development, and the middle one is broken. The **inner loop** is the agent writing and testing code. This works. Live browser, browser automation, test runners. The agent has tools to build with. The **outer loop** is production feedback coming back to development: bug reports, session replays, analytics. This mostly works, if slowly. The **middle loop** — a framework [Steve Yegge and Gene Kim introduced](https://steve-yegge.medium.com/six-new-tips-for-better-coding-with-agents-d4e9c86e42a9) in _Vibe Coding_, and that [Thoughtworks' Future of Software Development retreat](https://martinfowler.com/articles/exploring-gen-ai/humans-and-agents.html) later called its "strongest first-mover concept" — is where a human decides whether what the agent built is actually right before it ships. Right now, the tools for this are embarrassing. You get a preview link. You click around. Something feels off. You switch to chat and type "the animation on the second step feels janky" or "I think the spacing is wrong on the pricing card." The agent reads your words, guesses what you mean, tries again. You go back and forth four or five times. Maybe you take a screenshot and annotate it. Maybe you use Agentation to point at specific elements. Better than chat, but still a lossy translation of what you actually experienced. This is the communication layer for the fastest-growing workflow in software development, and it's screenshots and chat messages and annotated DOM elements. ![Sessions](/blog/images/agents-cant-see-3.jpg) ## Sessions as language This is why we built Subtext. But first, what do we mean by "session"? A session is the captured experience of someone (or something) using your application. Every click, scroll, navigation, pause, and error, recorded with full visual context and structured so that both humans can watch it and agents can read it. It's the lingua franca of digital interaction. If you've used Fullstory, Datadog, or any session replay tool, you know the concept. What's new is making sessions the communication layer between agents and humans, not just an analytics artifact. > Sessions are the native language of human-agent collaboration. When your agent builds something and deploys it to a preview, instead of you describing what's wrong, what if you just used the app? Your clicks, your pauses, your path through the interface, your annotations at specific moments. That's structured, timestamped, contextualized feedback. The agent doesn't have to interpret "the spacing feels off." It can see exactly where you stopped, what you looked at, and what you did next. And it goes both directions. When the agent finishes building, it doesn't just hand you a link. It captures its own session: driving the app, testing the flows, annotating what it did and why. "Fixed the re-render bug. See 0:34." You watch the replay. You see what the agent saw (or rather, what it _would_ have seen, if it could see). The session becomes the shared artifact. A full, replayable, annotated record of interaction with the actual application. It captures everything chat can't: timing, hesitation, the path someone actually took versus the path you assumed they'd take. ## Where this goes We built Subtext to give agents that shared artifact. It's session replay built for agents, a category we call [Agentic Session Review](/blog/a-map-not-a-movie). Your agent opens a real session the way it opens a file: the screenshots, the DOM and its diffs, the console, the network, the accessibility tree, read as tools and reasoned over. Not a video to watch. Not a summary to skim. Right now, a human reviews every agent-produced change before it ships. That's correct; we're early, and trust needs to be earned. But every session an agent reads is evidence, and every session you capture of the real thing going wrong is context it could never have guessed. The more the loop runs, the less there is to explain. And then there's agent-to-agent. When one agent hands off to another, a building agent to a QA agent, a frontend agent to a backend agent, the session becomes the handoff. Not API calls. Not structured messages. The actual experience, replayable, that the receiving agent can read for itself. > We're not building agents that write code faster. We're building the layer that lets them see. Subtext is out today. [Start free](https://subtext.fullstory.com), or point your agent at a real session: ```bash npx @subtextdev/subtext-wizard ```